

Why Incident Triage is a Key Element in Your MTTR

Yoram Pollack
BigPanda

One of the key performance indicators for IT Ops is MTTR (Mean-Time-To-Resolution). MTTR essentially measures the length of your incident management lifecycle: from detection; through assignment, triage and investigation; to remediation and resolution. IT Ops teams strive to shorten their incident management lifecycle and lower their MTTR, to meet their SLAs and maintain healthy infrastructures and services. But that's often easier said than done, with incident triage being a key factor in that challenge.

Why Incident Triage is Critical for Lowering MTTR

One of the main side effects of today's increasingly complex, hybrid and constantly changing IT environments is the proliferation of disparate ops teams, tools, apps and environments. This in turn leads to high volumes of IT incidents that lack full business context.

As a result, it has become increasingly difficult for first incident responders to triage incoming incidents: Without the ability to understand the incidents' severity based on their business priorities and their impact on services or customers, their routing information, and more — IT Ops teams often waste valuable time determining what to do next, and in doing so, lengthen the incident management lifecycle.

In essence, incident triage has grown to play a key role in determining MTTR in modern, hybrid environments.

Manual Incident Triage Can Be Painful

Because different applications and services have different impacts on customers, availability and revenue, when several incidents occur at the same time it is imperative for incident responders in IT Ops and NOC teams to identify the priority in which these incidents need to be dealt with, and how best to deal with each of them. For teams to be able to rapidly perform this triage, they need access to critical business context and business metrics:

■ The business severity of each incident

■ The services each of them impact

■ Whom to route them to

■ In which priority to do so

■ And other context based on the organization's relevant processes and services.

Without easy access to this information, the teams waste precious time tracking down relevant spreadsheets, runbooks, and other sources of tribal knowledge, as well as manually calculating the business metrics needed to help them understand the incidents' implications.

The more time that is spent on these manual steps, the longer the incident triage lasts.

And the longer that takes, the higher the probability that SLAs are violated, MTTR is kept high, and costs associated with high MTTR rapidly increase.

The solution? Automating incident triage.

Automating Incident Triage

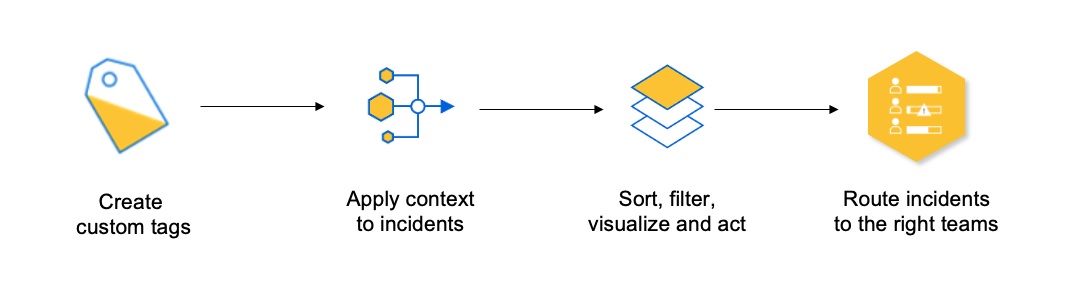
Incident triage can be automated by following several key guidelines:

■ The first step is to allow relevant business context information to reside on the incident level, rather than on the alert level. This can be done by creating custom tags for incidents that can hold this information and be acted upon (filtering, sorting etc).

■ The next step is to create simple yet robust formulas that allow operators to automatically calculate the values and metrics held by these tags. For example — calculate the SLA values in an SLA tag, based on the customer and the service to which the incident is referring. By automatically calculating the values and attaching them to the incident by using tags, the need to search for this information manually within tribal knowledge sources is eliminated, as is the need to calculate the values manually when the incident happens.

■ Now — provide filtering and sorting capabilities based on these tag values, and facilitate effective visualization of these tags alongside the incidents, so teams can easily make decisions and act on the incidents based on what they are seeing.

■ Finally — allow routing automation based on the tag values, so large volumes of incidents can be dealt with by relevant teams or automated resolution processes.

The Short and Long Term Advantages of Automating Incident Triage

The first advantage of incident triage automation is self-evident in all that was just discussed, mainly a shorter incident lifecycle — leading to improved performance and availability for apps and services. It's simple — lower MTTR equals better service.

But let's not forget two additional, substantial gains.

First — improved NOC productivity. By providing the above-mentioned capabilities, a substantial part of the incident lifecycle becomes simpler, and teams can collaborate better — lowering stress and effort across the board. Over time, the collected information can also be used for ongoing improvements in tools and processes.

And second — reclaimed FTE hours, an often “hidden” cost-reducer and revenue-generator. By reclaiming thousands of operational “fire-fighting” man-hours and utilizing them to improve and develop new services, enterprises not only reduce costs but also accelerate their business.

Yoram Pollack is Director of Product Marketing at BigPanda

The Latest

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...

Government agencies are largely misjudging their level of AI governance as the technology permeates their organization, according to Racing to Deploy: How Public Sector AI Adoption is Moving Faster Than the Foundations Needed to Support It, a new report from SolarWinds ...

Why Incident Triage is a Key Element in Your MTTR

Yoram Pollack
BigPanda

One of the key performance indicators for IT Ops is MTTR (Mean-Time-To-Resolution). MTTR essentially measures the length of your incident management lifecycle: from detection; through assignment, triage and investigation; to remediation and resolution. IT Ops teams strive to shorten their incident management lifecycle and lower their MTTR, to meet their SLAs and maintain healthy infrastructures and services. But that's often easier said than done, with incident triage being a key factor in that challenge.


Why Incident Triage is Critical for Lowering MTTR

One of the main side effects of today's increasingly complex, hybrid and constantly changing IT environments is the proliferation of disparate ops teams, tools, apps and environments. This in turn leads to high volumes of IT incidents that lack full business context.

As a result, it has become increasingly difficult for first incident responders to triage incoming incidents: Without the ability to understand the incidents' severity based on their business priorities and their impact on services or customers, their routing information, and more — IT Ops teams often waste valuable time determining what to do next, and in doing so, lengthen the incident management lifecycle.

In essence, incident triage has grown to play a key role in determining MTTR in modern, hybrid environments.

Manual Incident Triage Can Be Painful

Because different applications and services have different impacts on customers, availability and revenue, when several incidents occur at the same time it is imperative for incident responders in IT Ops and NOC teams to identify the priority in which these incidents need to be dealt with, and how best to deal with each of them. For teams to be able to rapidly perform this triage, they need access to critical business context and business metrics:

■ The business severity of each incident

■ The services each of them impact

■ Whom to route them to

■ In which priority to do so

■ And other context based on the organization's relevant processes and services.

Without easy access to this information, the teams waste precious time tracking down relevant spreadsheets, runbooks, and other sources of tribal knowledge, as well as manually calculating the business metrics needed to help them understand the incidents' implications.

The more time that is spent on these manual steps, the longer the incident triage lasts.

And the longer that takes, the higher the probability that SLAs are violated, MTTR is kept high, and costs associated with high MTTR rapidly increase.

The solution? Automating incident triage.

Automating Incident Triage

Incident triage can be automated by following several key guidelines:

■ The first step is to allow relevant business context information to reside on the incident level, rather than on the alert level. This can be done by creating custom tags for incidents that can hold this information and be acted upon (filtering, sorting etc).

■ The next step is to create simple yet robust formulas that allow operators to automatically calculate the values and metrics held by these tags. For example — calculate the SLA values in an SLA tag, based on the customer and the service to which the incident is referring. By automatically calculating the values and attaching them to the incident by using tags, the need to search for this information manually within tribal knowledge sources is eliminated, as is the need to calculate the values manually when the incident happens.

■ Now — provide filtering and sorting capabilities based on these tag values, and facilitate effective visualization of these tags alongside the incidents, so teams can easily make decisions and act on the incidents based on what they are seeing.

■ Finally — allow routing automation based on the tag values, so large volumes of incidents can be dealt with by relevant teams or automated resolution processes.


The Short and Long Term Advantages of Automating Incident Triage

The first advantage of incident triage automation is self-evident in all that was just discussed, mainly a shorter incident lifecycle — leading to improved performance and availability for apps and services. It's simple — lower MTTR equals better service.

But let's not forget two additional, substantial gains.

First — improved NOC productivity. By providing the above-mentioned capabilities, a substantial part of the incident lifecycle becomes simpler, and teams can collaborate better — lowering stress and effort across the board. Over time, the collected information can also be used for ongoing improvements in tools and processes.

And second — reclaimed FTE hours, an often “hidden” cost-reducer and revenue-generator. By reclaiming thousands of operational “fire-fighting” man-hours and utilizing them to improve and develop new services, enterprises not only reduce costs but also accelerate their business.

Yoram Pollack is Director of Product Marketing at BigPanda

The Latest

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...

Government agencies are largely misjudging their level of AI governance as the technology permeates their organization, according to Racing to Deploy: How Public Sector AI Adoption is Moving Faster Than the Foundations Needed to Support It, a new report from SolarWinds ...