

Engineers Waste 25% of the Work Week on Troubleshooting

It's time to rethink the industry's approach to observability in a cloud native world
Rachel Dines
Chronosphere

Driven by the need to create scalable, faster, and more agile systems, businesses are adopting cloud native approaches. But cloud native environments also come with an explosion of data and complexity that makes it harder for businesses to detect and remediate issues before everything comes to a screeching halt. Observability, if done right, can make it easier to mitigate these challenges and remediate incidents before they become major customer-impacting problems.

To understand the challenges teams face while working on cloud native environments — and what happens when their observability functions fall short — Chronosphere surveyed over 500 engineers and software developers. The culmination is the 2023 Cloud Native Observability Report: Overcoming Cloud Native Complexity, which details the promise and pitfalls of cloud native observability in 2023.

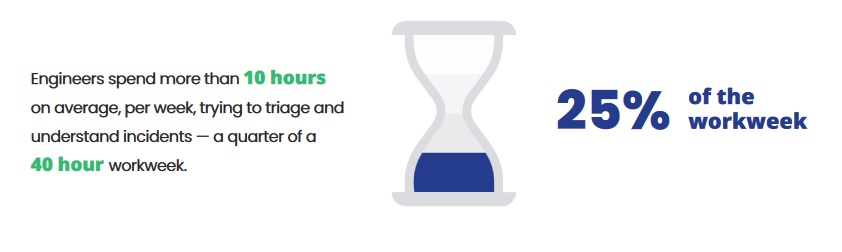
The report revealed that engineers waste an average of 10 hours or 25% of every work week trying to triage and understand incidents. Nearly all (96%) report that they spend most of their time resolving low level issues, and a third say that the stress of this constant troubleshooting is disrupting their personal lives. The aggregation of lost hours is costing US businesses over $44 billion productivity each year. This lack of efficiency is especially troublesome in today's economy where everyone is being asked to do more with less and watching the bottom line has become today's business mantra.

The silver lining is that observability offers massive benefits beyond remediation of incidents. 67% of those surveyed say having a strong observability function provides the foundation for all business value and 71% say their business can't innovate effectively without good observability. Yet, paradoxically, most surveyed aren't satisfied with their current solution, saying it's too slow, lacks context, requires a lot of time and effort, and is generally unhelpful.

All of this points to the conclusion that observability is required for business success — and perhaps business survival — but that the current approaches and solutions need to be completely rethought if they are to be sustainable in what is becoming a cloud native world.

What does a strong observability solution look like? It's not checking boxes on metrics, tracing, and logs — they are a means to an end. Strong observability enables teams to know, triage and understand so they can have quicker and better outcomes. The good news is that teams with a holistic plan backed by a modern observability vendor can provide a boost over other options. In fact, those using a vendor solution are detecting issues 65% faster than those without a cohesive approach. The survey also notes businesses using vendor solutions are three times more satisfied with their approach to observability than those using home-built solutions.

Chart the right course and observability can efficiently and effectively safeguard your business from incidents that jeopardize your brand. For those that take a wrong turn, it's often at their own peril. Without effective solutions, engineering talent will be lost, time that could have been spent on innovation will be wasted, and companies will be at risk of losing customers and significant revenue.

Rachel Dines is Head of Product and Developer Marketing at Chronosphere

Hot Topics

The Latest

AI observability serves several roles across an organization. AI engineers use it to build, evaluate, and improve AI systems. SREs use it to operate those systems reliably and efficiently in production, including managing their cost. Leaders need it to connect AI behavior and operational performance to business outcomes. The common need is a clear understanding of whether AI systems are delivering the intended result ...

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...

Engineers Waste 25% of the Work Week on Troubleshooting

It's time to rethink the industry's approach to observability in a cloud native world
Rachel Dines
Chronosphere

Driven by the need to create scalable, faster, and more agile systems, businesses are adopting cloud native approaches. But cloud native environments also come with an explosion of data and complexity that makes it harder for businesses to detect and remediate issues before everything comes to a screeching halt. Observability, if done right, can make it easier to mitigate these challenges and remediate incidents before they become major customer-impacting problems.

To understand the challenges teams face while working on cloud native environments — and what happens when their observability functions fall short — Chronosphere surveyed over 500 engineers and software developers. The culmination is the 2023 Cloud Native Observability Report: Overcoming Cloud Native Complexity, which details the promise and pitfalls of cloud native observability in 2023.

The report revealed that engineers waste an average of 10 hours or 25% of every work week trying to triage and understand incidents. Nearly all (96%) report that they spend most of their time resolving low level issues, and a third say that the stress of this constant troubleshooting is disrupting their personal lives. The aggregation of lost hours is costing US businesses over $44 billion productivity each year. This lack of efficiency is especially troublesome in today's economy where everyone is being asked to do more with less and watching the bottom line has become today's business mantra.


The silver lining is that observability offers massive benefits beyond remediation of incidents. 67% of those surveyed say having a strong observability function provides the foundation for all business value and 71% say their business can't innovate effectively without good observability. Yet, paradoxically, most surveyed aren't satisfied with their current solution, saying it's too slow, lacks context, requires a lot of time and effort, and is generally unhelpful.

All of this points to the conclusion that observability is required for business success — and perhaps business survival — but that the current approaches and solutions need to be completely rethought if they are to be sustainable in what is becoming a cloud native world.

What does a strong observability solution look like? It's not checking boxes on metrics, tracing, and logs — they are a means to an end. Strong observability enables teams to know, triage and understand so they can have quicker and better outcomes. The good news is that teams with a holistic plan backed by a modern observability vendor can provide a boost over other options. In fact, those using a vendor solution are detecting issues 65% faster than those without a cohesive approach. The survey also notes businesses using vendor solutions are three times more satisfied with their approach to observability than those using home-built solutions.

Chart the right course and observability can efficiently and effectively safeguard your business from incidents that jeopardize your brand. For those that take a wrong turn, it's often at their own peril. Without effective solutions, engineering talent will be lost, time that could have been spent on innovation will be wasted, and companies will be at risk of losing customers and significant revenue.

Rachel Dines is Head of Product and Developer Marketing at Chronosphere

Hot Topics

The Latest

AI observability serves several roles across an organization. AI engineers use it to build, evaluate, and improve AI systems. SREs use it to operate those systems reliably and efficiently in production, including managing their cost. Leaders need it to connect AI behavior and operational performance to business outcomes. The common need is a clear understanding of whether AI systems are delivering the intended result ...

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...