

AWS Monitoring: Metrics You Need to Monitor

Sujitha Paduchuri
ManageEngine

AWS is a cloud-based computing platform known for its reliability, scalability, and flexibility. However, as helpful as its comprehensive infrastructure is, disparate elements and numerous siloed components make it difficult for admins to visualize the cloud performance in detail. It requires meticulous monitoring techniques and deep visibility to understand cloud performance and analyze operational efficiency in detail to ensure seamless cloud operations.

Here are the crucial metrics you need to keep track of while monitoring your AWS cloud environments to ensure high efficiency and uninterrupted cloud services.

1. CPU usage

The cloud doesn't just make your applications and resources accessible; it makes them organized so teams can manage and coordinate efficiently while catering to an extensive workload. When any service or IT component is actively in use, it consumes CPU resources. This is because the CPU is responsible for executing the instructions and calculations that drive the service's functionality. The cloud is no exception, especially for AWS Compute resources that run your workloads (EC2 or ECS).

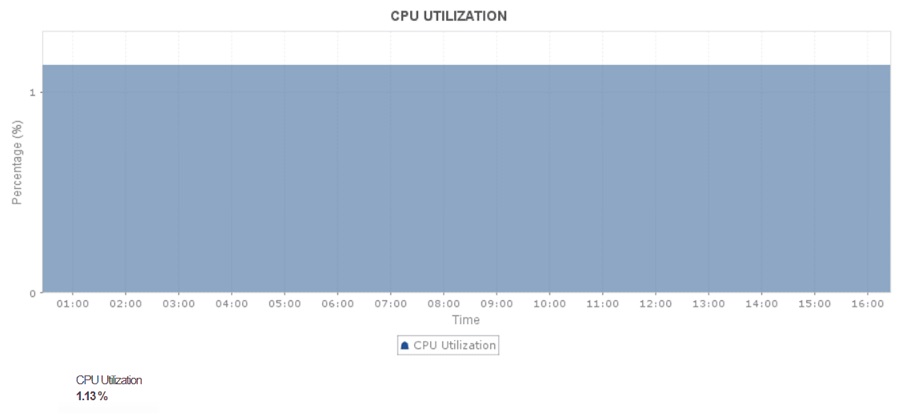
Monitoring and understanding CPU utilization trends help you determine whether the instances are over- or under-utilizing the CPU.

By tracking CPU usage, you can pinpoint applications and code algorithms that are consuming a major part of your resources, and balance the workload accordingly to optimize CPU utilization. If it is not optimized at the component-level, it could lead to starvation among the components, apart from those that are over-consuming the CPU. To avoid severe issues like application lag and crashes due to CPU starvation, set up alarms for different levels of threshold breaches and act in time to optimize CPU usage.

2. Memory

Memory plays a key role in keeping a cloud environment intact. It supports cloud stability by storing data for fast access, preventing slowdowns, and avoiding crashes under high loads. With insufficient memory, it would be difficult to scale up cloud services, maintain productivity, and ensure smooth cloud operations, especially among dynamic cloud environments.

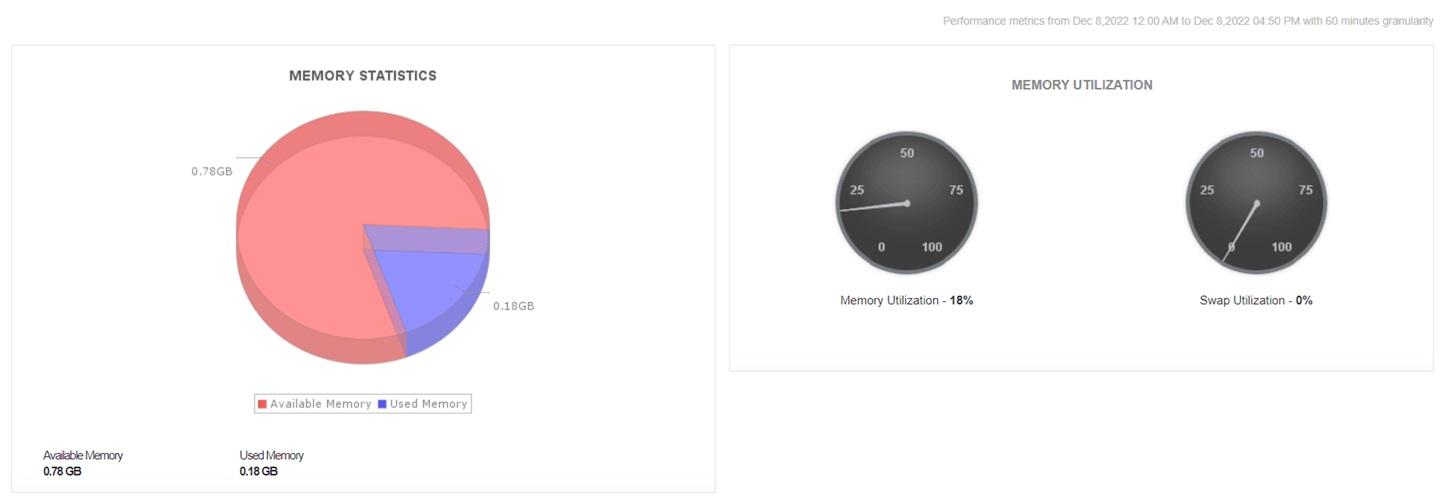
Monitoring memory utilization and allocation helps admins identify inefficient resource allocation that can lead to cloud performance issues, downtime, or unnecessary cloud costs. You can't compromise on this KPI, as it helps you identify and rectify issues in scaling and allocation.
Image
ManageEngine


Especially in the AWS cloud, it is important to be precise while scaling. In instances like ECS and EKS, allocating the right amount of memory to the tasks and processes that cater to larger workloads keeps them from running out of resources, ensuring seamless cloud operation. It also partially eliminates the scope for issues like memory leaks. On the contrary, it's equally important to ensure the smaller workloads and other resources are assigned adequate memory and to downsize the resources that are not in use.
Image
ManageEngine


Knowing the right amount of memory required by the tasks no longer remains a challenge when you are keeping track of memory usage by each instance down to the last container, database, pod, and nod in real time. Trend analysis helps you understand the nature of your workloads and helps you predict future requirements.

3. Disk throughput

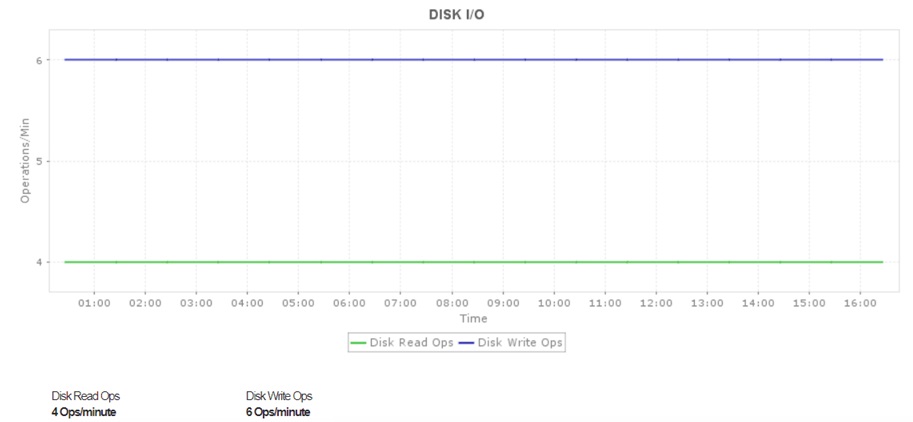
Disk I/O shows the amount of data being read from and fed to your AWS cloud in a given time interval. Tracking the volume of this data in bytes helps you easily understand data traffic and identify potential bottlenecks before they lead to notorious incidents like downtime or worse, crashes.
Image
ManageEngine


How does simply identifying bottlenecks help?

It doesn't. But once you spot a potential bottleneck, you can reduce the load on the specific instance by configuring a caching mechanism, which can take the load of long queues and performance anomalies off your back.

4. Requests

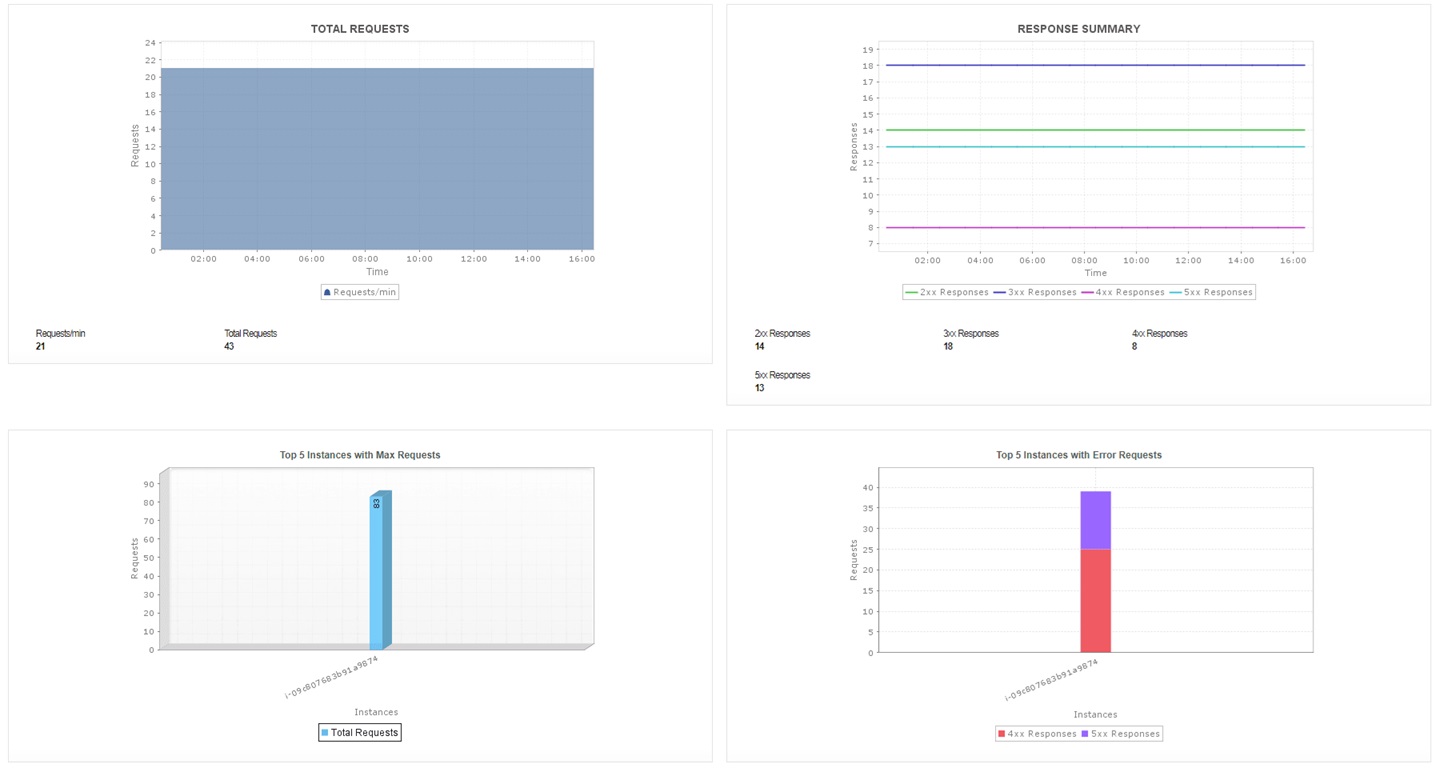
The request count metric sheds light on the total number of requests raised per instance in your AWS ecosystem.

Monitoring AWS cloud to keep a track of request rates helps you identify spiking request traffic and troubleshoot respective instances for potential misconfiguration or DNS-related issues. Visibility into requests helps admins visualize the frequency and nature of incoming and outgoing service transactions. This allows them to understand resource requirements, identify performance anomalies, and prevent potential outages and service interruptions. Setting up adaptive threshold profiles keeps you informed about peaking request traffic and eliminates false alarms, especially when serving numerous workloads ranging from web applications to big data analytics.
Image
ManageEngine


5. Latency

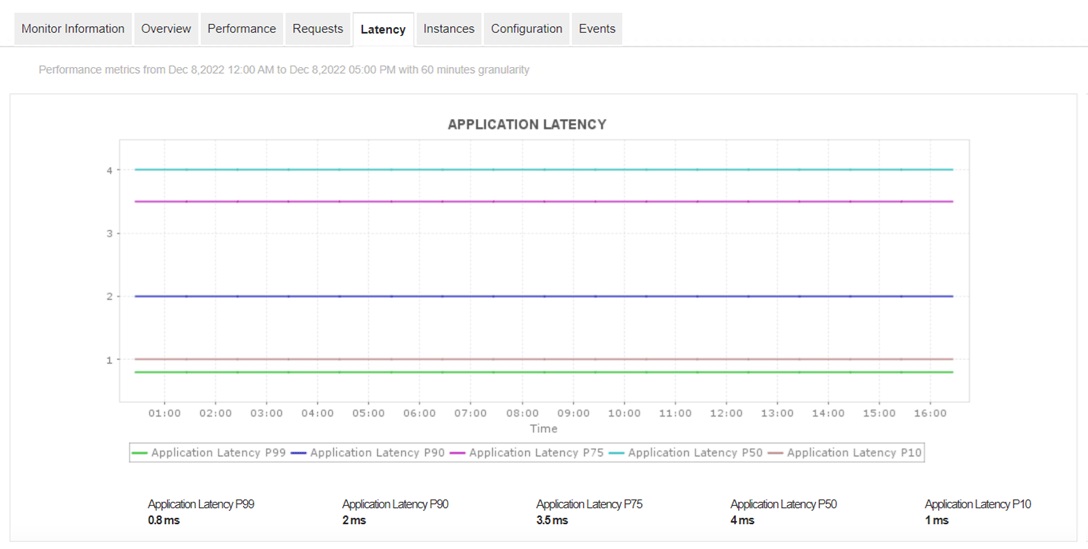
is the interval of time taken by an application to respond to a user request. High latency indicates poor AWS cloud performance. It is usually observed in AWS cloud environments with poor network connections, misconfigured host servers, or improper dependencies among web servers.
Image
ManageEngine


Monitoring latency in AWS allows admins to identify issues like network congestion, misconfigurations, slow transactions, and weakly performing components efficiently. Without proper visualization of latency in AWS, many performance issues like high response times, delayed transactions, and many more could go unnoticed and have a major negative impact on the cloud experience. Monitoring server latency in real time helps identify slow components, enabling quicker issue fixes and smoother cloud operations.

Why choose a unified monitoring solution?

Monitoring your AWS environment from AWS CloudWatch and other native monitoring tools might be handy at first. Once you start monitoring large-scale environments across multiple regions, CloudWatch can become cumbersome. Limitations include:

  • Limited detail for in-depth analysis.
    • Basic alerting features without advanced anomaly detection or integration options (eg: Slack).

This is why it's essential to find a monitoring tool that can accommodate your disparate IT environment and provide deep visibility into your IT infrastructure.

ManageEngine Applications Manager offers monitoring support for over 150 technologies, including cloud native and on premise components. It can accommodate numerous cloud providers, i.e., AWS, Azure, GCP, Oracle, and OpenStack. You can get extensive performance analytics, such as code-level diagnostics and user experience monitoring, which are beyond the scope of CloudWatch. You also get superior visualization capabilities in the form of more intuitive dashboards that help teams quickly identify performance issues. 
Sujitha Paduchuri is a Content Writer at ManageEngine, a division of Zohocorp

Hot Topics

The Latest

Two years ago, almost every customer conversation about AI started with the same questions: Which model should we use? What can it do? Is it ready for the enterprise? Today, those discussions have moved on. CIOs are far more interested in how to govern AI, integrate it with existing systems, prepare their workforce and make it part of everyday operations. The challenge is no longer to prove that AI can deliver value. It's instead about how to embed AI into the business in a way that's secure, scalable and delivers measurable outcomes ...


Two things happened to production incidents between 2023 and now, and they did not happen at the same speed. The first is that a class of dependency that barely existed three years ago now accounts for one incident in ten. Incidents disclosed by AI model and AI application providers rose from 1.7% of all disclosed unplanned incidents in 2023 to 10.7% in 2026 year to date, roughly a sixfold rise; that counts only incidents at AI companies themselves, so the true share is higher. The second is that the time to close an incident has not come down ...

When an AI assistant gives an incomplete or incorrect answer, teams often blame the model. They adjust prompts, switch models, increase context windows or test a new retrieval strategy. However the model may not be a problem. In many enterprise AI workflows, the problem begins inside the document-ingestion pipeline ...

If you talk to any security or observability teams right now, they're all fighting the same fire: their tooling was built to ingest X, but their sources are pumping Y and soon to be doing Z. The knee-jerk reaction is always the same: we need more platform. However, this reaction is wrong. Let me explain why, because the solution to this problem is foundational, not financial. Instead of hurling yet more money at the problem, make sure you've done what's needed upstream ...

Rapid AI adoption and the unique ways AI workloads operate is redefining the scope and structure of what these teams must deliver. This shift is forcing organizations to rethink how they manage scale, automation, and control, according to The State of SRE and Platform Engineering 2026, a new report from Dynatrace ...

AI is usually talked about as a software tool, but it also depends heavily on the network behind it. Whether a company is using AI for chatbots, automation, monitoring, analytics, or employee support, all of that information has to move across the network in a reliable and secure way. That means AI is not just an application decision. It is also an infrastructure decision. Before organizations rush into AI, they should ask a simple question: Is our network ready to support it? ...

Enterprise AI often lacks governed access to where business processes actually execute. Without that access, AI agents may be able to reason, but they cannot operate reliably across enterprise workflows. For AI agents to effectively carry out workflows, they will require integration-layer context and controls. Organizations can implement these prerequisites by providing AI with managed access to the middleware layer ...

Enterprise networks rarely behave the same way for very long. A routing adjustment in one region may unexpectedly alter application performance in another. A cloud migration may introduce hidden dependencies that go unnoticed until an outage occurs. All the while, the network is managed by several different teams, each of whom use different tool sets — and as a result, have different views of the network ... There’s usually an engineer who remembers why traffic fails over a certain way between sites, or which transparent firewall was added where. The problem is that human memory cannot scale alongside enterprise-scale networks ...

Ask an infrastructure team how confident they are in their ability to govern AI, and most will tell you they've got it handled. A recent survey of 406 IT decision-makers and platform engineering leaders found 86% expressing exactly that confidence. Ask the same group whether they have a formal written AI governance policy, and the number drops to 30%, according to Spacelift's Infrastructure Automation Report ...

In MEAN TIME TO INSIGHT Episode 27, Shamus McGillicuddy, EMA VP of Research, Network Infrastructure and Operations, and Parker Hathcock, EMA Research Director covering IT Service/Operations (ServiceOps), discuss observability unification in modern IT operations ... 

AWS Monitoring: Metrics You Need to Monitor

Sujitha Paduchuri
ManageEngine

AWS is a cloud-based computing platform known for its reliability, scalability, and flexibility. However, as helpful as its comprehensive infrastructure is, disparate elements and numerous siloed components make it difficult for admins to visualize the cloud performance in detail. It requires meticulous monitoring techniques and deep visibility to understand cloud performance and analyze operational efficiency in detail to ensure seamless cloud operations.

Here are the crucial metrics you need to keep track of while monitoring your AWS cloud environments to ensure high efficiency and uninterrupted cloud services.

1. CPU usage

The cloud doesn't just make your applications and resources accessible; it makes them organized so teams can manage and coordinate efficiently while catering to an extensive workload. When any service or IT component is actively in use, it consumes CPU resources. This is because the CPU is responsible for executing the instructions and calculations that drive the service's functionality. The cloud is no exception, especially for AWS Compute resources that run your workloads (EC2 or ECS).

Monitoring and understanding CPU utilization trends help you determine whether the instances are over- or under-utilizing the CPU.

By tracking CPU usage, you can pinpoint applications and code algorithms that are consuming a major part of your resources, and balance the workload accordingly to optimize CPU utilization. If it is not optimized at the component-level, it could lead to starvation among the components, apart from those that are over-consuming the CPU. To avoid severe issues like application lag and crashes due to CPU starvation, set up alarms for different levels of threshold breaches and act in time to optimize CPU usage.

2. Memory

Memory plays a key role in keeping a cloud environment intact. It supports cloud stability by storing data for fast access, preventing slowdowns, and avoiding crashes under high loads. With insufficient memory, it would be difficult to scale up cloud services, maintain productivity, and ensure smooth cloud operations, especially among dynamic cloud environments.

Monitoring memory utilization and allocation helps admins identify inefficient resource allocation that can lead to cloud performance issues, downtime, or unnecessary cloud costs. You can't compromise on this KPI, as it helps you identify and rectify issues in scaling and allocation.

Image
ManageEngine


Especially in the AWS cloud, it is important to be precise while scaling. In instances like ECS and EKS, allocating the right amount of memory to the tasks and processes that cater to larger workloads keeps them from running out of resources, ensuring seamless cloud operation. It also partially eliminates the scope for issues like memory leaks. On the contrary, it's equally important to ensure the smaller workloads and other resources are assigned adequate memory and to downsize the resources that are not in use.

Image
ManageEngine


Knowing the right amount of memory required by the tasks no longer remains a challenge when you are keeping track of memory usage by each instance down to the last container, database, pod, and nod in real time. Trend analysis helps you understand the nature of your workloads and helps you predict future requirements.

3. Disk throughput

Disk I/O shows the amount of data being read from and fed to your AWS cloud in a given time interval. Tracking the volume of this data in bytes helps you easily understand data traffic and identify potential bottlenecks before they lead to notorious incidents like downtime or worse, crashes.

Image
ManageEngine


How does simply identifying bottlenecks help?

It doesn't. But once you spot a potential bottleneck, you can reduce the load on the specific instance by configuring a caching mechanism, which can take the load of long queues and performance anomalies off your back.

4. Requests

The request count metric sheds light on the total number of requests raised per instance in your AWS ecosystem.

Monitoring AWS cloud to keep a track of request rates helps you identify spiking request traffic and troubleshoot respective instances for potential misconfiguration or DNS-related issues. Visibility into requests helps admins visualize the frequency and nature of incoming and outgoing service transactions. This allows them to understand resource requirements, identify performance anomalies, and prevent potential outages and service interruptions. Setting up adaptive threshold profiles keeps you informed about peaking request traffic and eliminates false alarms, especially when serving numerous workloads ranging from web applications to big data analytics.

Image
ManageEngine


5. Latency

is the interval of time taken by an application to respond to a user request. High latency indicates poor AWS cloud performance. It is usually observed in AWS cloud environments with poor network connections, misconfigured host servers, or improper dependencies among web servers.

Image
ManageEngine


Monitoring latency in AWS allows admins to identify issues like network congestion, misconfigurations, slow transactions, and weakly performing components efficiently. Without proper visualization of latency in AWS, many performance issues like high response times, delayed transactions, and many more could go unnoticed and have a major negative impact on the cloud experience. Monitoring server latency in real time helps identify slow components, enabling quicker issue fixes and smoother cloud operations.

Why choose a unified monitoring solution?

Monitoring your AWS environment from AWS CloudWatch and other native monitoring tools might be handy at first. Once you start monitoring large-scale environments across multiple regions, CloudWatch can become cumbersome. Limitations include:

  • Limited detail for in-depth analysis.
    • Basic alerting features without advanced anomaly detection or integration options (eg: Slack).

This is why it's essential to find a monitoring tool that can accommodate your disparate IT environment and provide deep visibility into your IT infrastructure.

ManageEngine Applications Manager offers monitoring support for over 150 technologies, including cloud native and on premise components. It can accommodate numerous cloud providers, i.e., AWS, Azure, GCP, Oracle, and OpenStack. You can get extensive performance analytics, such as code-level diagnostics and user experience monitoring, which are beyond the scope of CloudWatch. You also get superior visualization capabilities in the form of more intuitive dashboards that help teams quickly identify performance issues. 

Sujitha Paduchuri is a Content Writer at ManageEngine, a division of Zohocorp

Hot Topics

The Latest

Two years ago, almost every customer conversation about AI started with the same questions: Which model should we use? What can it do? Is it ready for the enterprise? Today, those discussions have moved on. CIOs are far more interested in how to govern AI, integrate it with existing systems, prepare their workforce and make it part of everyday operations. The challenge is no longer to prove that AI can deliver value. It's instead about how to embed AI into the business in a way that's secure, scalable and delivers measurable outcomes ...


Two things happened to production incidents between 2023 and now, and they did not happen at the same speed. The first is that a class of dependency that barely existed three years ago now accounts for one incident in ten. Incidents disclosed by AI model and AI application providers rose from 1.7% of all disclosed unplanned incidents in 2023 to 10.7% in 2026 year to date, roughly a sixfold rise; that counts only incidents at AI companies themselves, so the true share is higher. The second is that the time to close an incident has not come down ...

When an AI assistant gives an incomplete or incorrect answer, teams often blame the model. They adjust prompts, switch models, increase context windows or test a new retrieval strategy. However the model may not be a problem. In many enterprise AI workflows, the problem begins inside the document-ingestion pipeline ...

If you talk to any security or observability teams right now, they're all fighting the same fire: their tooling was built to ingest X, but their sources are pumping Y and soon to be doing Z. The knee-jerk reaction is always the same: we need more platform. However, this reaction is wrong. Let me explain why, because the solution to this problem is foundational, not financial. Instead of hurling yet more money at the problem, make sure you've done what's needed upstream ...

Rapid AI adoption and the unique ways AI workloads operate is redefining the scope and structure of what these teams must deliver. This shift is forcing organizations to rethink how they manage scale, automation, and control, according to The State of SRE and Platform Engineering 2026, a new report from Dynatrace ...

AI is usually talked about as a software tool, but it also depends heavily on the network behind it. Whether a company is using AI for chatbots, automation, monitoring, analytics, or employee support, all of that information has to move across the network in a reliable and secure way. That means AI is not just an application decision. It is also an infrastructure decision. Before organizations rush into AI, they should ask a simple question: Is our network ready to support it? ...

Enterprise AI often lacks governed access to where business processes actually execute. Without that access, AI agents may be able to reason, but they cannot operate reliably across enterprise workflows. For AI agents to effectively carry out workflows, they will require integration-layer context and controls. Organizations can implement these prerequisites by providing AI with managed access to the middleware layer ...

Enterprise networks rarely behave the same way for very long. A routing adjustment in one region may unexpectedly alter application performance in another. A cloud migration may introduce hidden dependencies that go unnoticed until an outage occurs. All the while, the network is managed by several different teams, each of whom use different tool sets — and as a result, have different views of the network ... There’s usually an engineer who remembers why traffic fails over a certain way between sites, or which transparent firewall was added where. The problem is that human memory cannot scale alongside enterprise-scale networks ...

Ask an infrastructure team how confident they are in their ability to govern AI, and most will tell you they've got it handled. A recent survey of 406 IT decision-makers and platform engineering leaders found 86% expressing exactly that confidence. Ask the same group whether they have a formal written AI governance policy, and the number drops to 30%, according to Spacelift's Infrastructure Automation Report ...

In MEAN TIME TO INSIGHT Episode 27, Shamus McGillicuddy, EMA VP of Research, Network Infrastructure and Operations, and Parker Hathcock, EMA Research Director covering IT Service/Operations (ServiceOps), discuss observability unification in modern IT operations ...