
How to Speed Up Incidents with a Lot of Cooks in the Kitchen

Anirban Chatterjee

In today's complex, dynamic IT environments, the proliferation of disparate IT Ops, NOC, DevOps, and SRE teams and tools is a given — and usually considered a necessity. This leads to the inevitable truth that when an incident happens, often the biggest challenge is collaborating between these teams to understand what happened and resolve the issue. Inefficiencies suffered during this critical stage can have huge impacts on how much each incident costs the business.

I recently sat down (virtually) with Sid Roy, VP of Client Services at Scicom, to get a deeper understanding of how IT leaders can more effectively size up these inefficiencies and eliminate them.

The Cost of IT Incidents

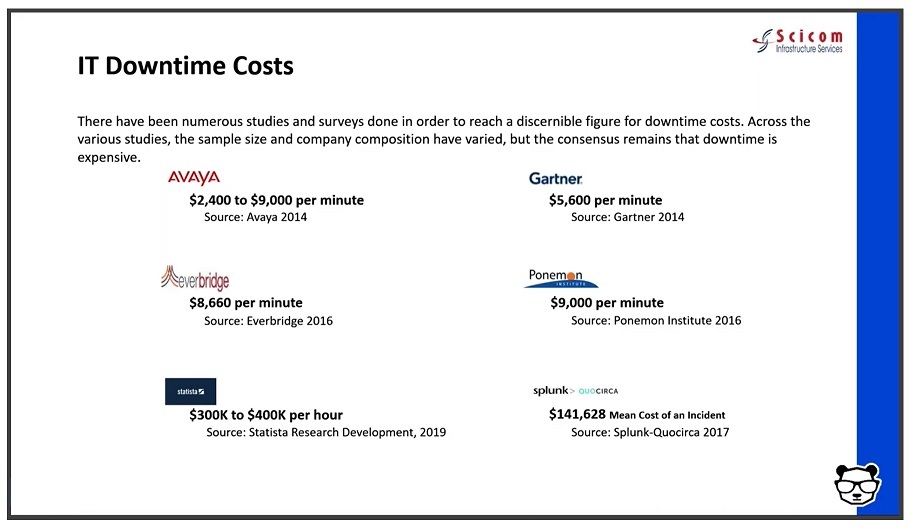
When asked what a minute of downtime costs, analysts and vendors may provide different answers — but they are more or less aligned around the same order of magnitude — several thousands of dollars per minute. And with an average of 5 major incidents a month, at an average time of 6 hours for resolution — this easily amounts to millions of dollars a year.

The three key drivers of these costs are:

Staffing and team member costs: It includes FTEs, consultants, and overhead — when other teams are pulled in to deal with the incident. For many organizations, this can include offshore incident response teams.

The direct and indirect costs of an IT incident: This includes your infrastructure or capital expenditures like software licenses for monitoring, log and event management, notification, ticketing, collaboration, etc.

The business impact of an IT incident: This is one of the most challenging and unpredictable variable costs to calculate or manage, and is often the highest of all three drivers. It includes revenue loss/delay or reduction due to a major incident and the profit or loss due to brand or goodwill impact. It also includes inefficiencies suffered by other parts of the business when critical services they depend on are degraded or unavailable.

Fragmented Teams Magnify the Challenge

The incident volume, complexity, and throughput obviously affect the number of people and time needed to deal with them and often drive more indirect costs as needed resources pile up. To save on these millions of dollars of costs, you need to be able to collaborate and lower MTTR. As mentioned above, this becomes a challenge in agile IT environments.

To help streamline operations, teams need to start asking and answering several key questions:

■ Do you have an up-to-date map of your critical services?

■ Are they prioritized by business criticality (revenue, number of customers, other supported services in the supply chain)?

■ What are the upstream and downstream dependencies of these applications?

■ Have you identified the major infrastructure and application elements in your environment?

■ Are you aligned with the owners of these systems?

■ Do you have real-time knowledge of changes being done to the infrastructure and applications?

■ Do you have monitoring gaps?

■ Which monitoring tools provide you with the best value?

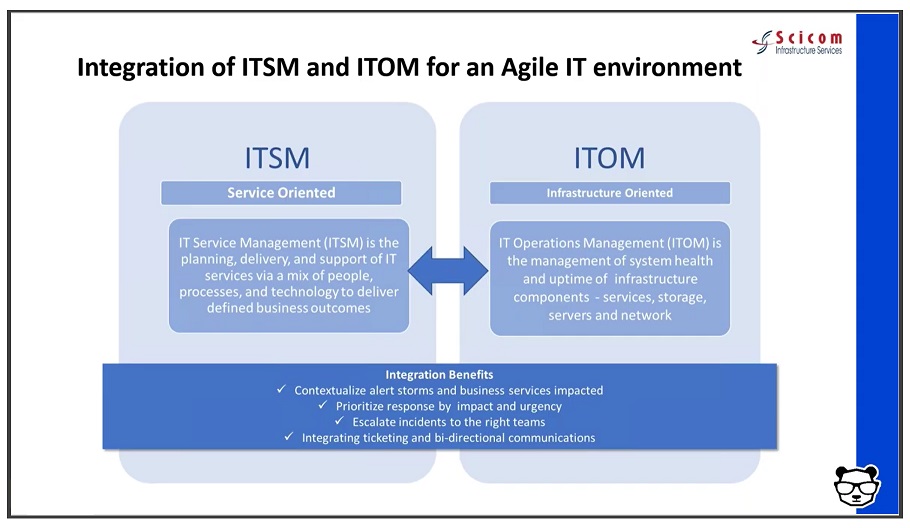
Answering these questions involves overcoming fragmentation across teams of people, processes, and tools — essentially integrating ITSM and ITOM to enjoy the benefits of contextual full-stack visibility and streamlined processes within the organization.

The Right Combination

What is the right combination of people, processes, and tools we just discussed? Here are the two main guidelines:

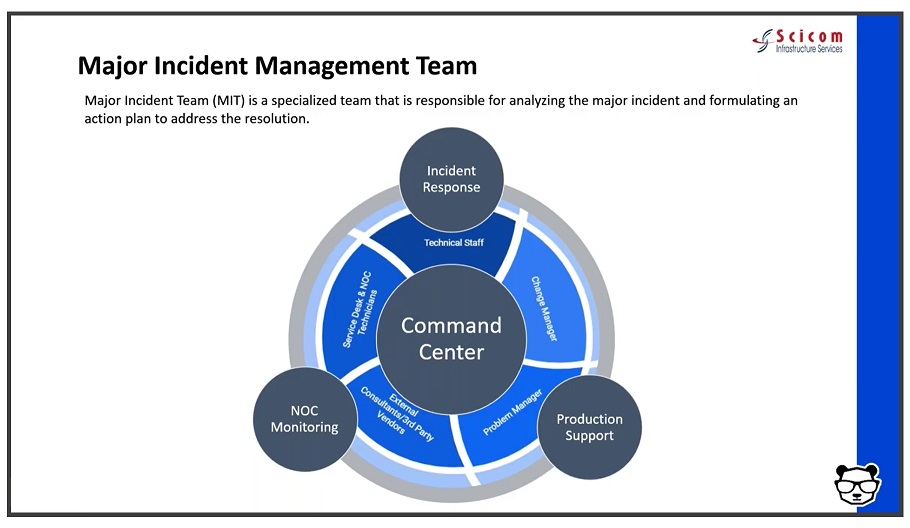
Set up a major incident management team- to optimally benefit from your existing staff.

This team includes three vital roles:

- The incident manager/incident response commander. A designated role in charge of declaring a major incident and taking ownership of it. Their job is to essentially stop the bleeding of revenue and costs.

- The NOC/monitoring team. This is your front line of defense. When things go bump in the night or boom in the day, they're the ones picking it up with their “eyes on the glass” — 24/7. And they're in charge of reporting and creating full situational awareness for the incident command through bidirectional communications.

- The production support. The team that actually effects the required changes and executes the remediating action.

Deploy event correlation and automation tools to enable the incident management team.

These tools are key, allowing your team to do all the above.

First, correlate the alerts your monitoring and observability tools create into a drastically reduced number of high-level, insight-rich incidents by using Machine Learning and AI. Add context to these incidents by ingesting and understanding topology sources as well. This creates the needed full-stack visibility and situational awareness.

Then use ML and AI to determine the root cause of these incidents, including correlating them with data streams from your change tools: CI/CD, orchestration, change management, and auditing — to identify whether any changes were done in your environment are causing these incidents.

Finally — automate as many manual processes as you can to free your IT Ops team from time-consuming tasks. By integrating with collaboration tools — you can also enable the above-mentioned bi-directional communications.

The Latest

Two years ago, almost every customer conversation about AI started with the same questions: Which model should we use? What can it do? Is it ready for the enterprise? Today, those discussions have moved on. CIOs are far more interested in how to govern AI, integrate it with existing systems, prepare their workforce and make it part of everyday operations. The challenge is no longer to prove that AI can deliver value. It's instead about how to embed AI into the business in a way that's secure, scalable and delivers measurable outcomes ...


Two things happened to production incidents between 2023 and now, and they did not happen at the same speed. The first is that a class of dependency that barely existed three years ago now accounts for one incident in ten. Incidents disclosed by AI model and AI application providers rose from 1.7% of all disclosed unplanned incidents in 2023 to 10.7% in 2026 year to date, roughly a sixfold rise; that counts only incidents at AI companies themselves, so the true share is higher. The second is that the time to close an incident has not come down ...

When an AI assistant gives an incomplete or incorrect answer, teams often blame the model. They adjust prompts, switch models, increase context windows or test a new retrieval strategy. However the model may not be a problem. In many enterprise AI workflows, the problem begins inside the document-ingestion pipeline ...

If you talk to any security or observability teams right now, they're all fighting the same fire: their tooling was built to ingest X, but their sources are pumping Y and soon to be doing Z. The knee-jerk reaction is always the same: we need more platform. However, this reaction is wrong. Let me explain why, because the solution to this problem is foundational, not financial. Instead of hurling yet more money at the problem, make sure you've done what's needed upstream ...

Rapid AI adoption and the unique ways AI workloads operate is redefining the scope and structure of what these teams must deliver. This shift is forcing organizations to rethink how they manage scale, automation, and control, according to The State of SRE and Platform Engineering 2026, a new report from Dynatrace ...

AI is usually talked about as a software tool, but it also depends heavily on the network behind it. Whether a company is using AI for chatbots, automation, monitoring, analytics, or employee support, all of that information has to move across the network in a reliable and secure way. That means AI is not just an application decision. It is also an infrastructure decision. Before organizations rush into AI, they should ask a simple question: Is our network ready to support it? ...

Enterprise AI often lacks governed access to where business processes actually execute. Without that access, AI agents may be able to reason, but they cannot operate reliably across enterprise workflows. For AI agents to effectively carry out workflows, they will require integration-layer context and controls. Organizations can implement these prerequisites by providing AI with managed access to the middleware layer ...

Enterprise networks rarely behave the same way for very long. A routing adjustment in one region may unexpectedly alter application performance in another. A cloud migration may introduce hidden dependencies that go unnoticed until an outage occurs. All the while, the network is managed by several different teams, each of whom use different tool sets — and as a result, have different views of the network ... There’s usually an engineer who remembers why traffic fails over a certain way between sites, or which transparent firewall was added where. The problem is that human memory cannot scale alongside enterprise-scale networks ...

Ask an infrastructure team how confident they are in their ability to govern AI, and most will tell you they've got it handled. A recent survey of 406 IT decision-makers and platform engineering leaders found 86% expressing exactly that confidence. Ask the same group whether they have a formal written AI governance policy, and the number drops to 30%, according to Spacelift's Infrastructure Automation Report ...

In MEAN TIME TO INSIGHT Episode 27, Shamus McGillicuddy, EMA VP of Research, Network Infrastructure and Operations, and Parker Hathcock, EMA Research Director covering IT Service/Operations (ServiceOps), discuss observability unification in modern IT operations ... 

How to Speed Up Incidents with a Lot of Cooks in the Kitchen

Anirban Chatterjee

In today's complex, dynamic IT environments, the proliferation of disparate IT Ops, NOC, DevOps, and SRE teams and tools is a given — and usually considered a necessity. This leads to the inevitable truth that when an incident happens, often the biggest challenge is collaborating between these teams to understand what happened and resolve the issue. Inefficiencies suffered during this critical stage can have huge impacts on how much each incident costs the business.

I recently sat down (virtually) with Sid Roy, VP of Client Services at Scicom, to get a deeper understanding of how IT leaders can more effectively size up these inefficiencies and eliminate them.

The Cost of IT Incidents

When asked what a minute of downtime costs, analysts and vendors may provide different answers — but they are more or less aligned around the same order of magnitude — several thousands of dollars per minute. And with an average of 5 major incidents a month, at an average time of 6 hours for resolution — this easily amounts to millions of dollars a year.


The three key drivers of these costs are:

Staffing and team member costs: It includes FTEs, consultants, and overhead — when other teams are pulled in to deal with the incident. For many organizations, this can include offshore incident response teams.

The direct and indirect costs of an IT incident: This includes your infrastructure or capital expenditures like software licenses for monitoring, log and event management, notification, ticketing, collaboration, etc.

The business impact of an IT incident: This is one of the most challenging and unpredictable variable costs to calculate or manage, and is often the highest of all three drivers. It includes revenue loss/delay or reduction due to a major incident and the profit or loss due to brand or goodwill impact. It also includes inefficiencies suffered by other parts of the business when critical services they depend on are degraded or unavailable.

Fragmented Teams Magnify the Challenge

The incident volume, complexity, and throughput obviously affect the number of people and time needed to deal with them and often drive more indirect costs as needed resources pile up. To save on these millions of dollars of costs, you need to be able to collaborate and lower MTTR. As mentioned above, this becomes a challenge in agile IT environments.

To help streamline operations, teams need to start asking and answering several key questions:

■ Do you have an up-to-date map of your critical services?

■ Are they prioritized by business criticality (revenue, number of customers, other supported services in the supply chain)?

■ What are the upstream and downstream dependencies of these applications?

■ Have you identified the major infrastructure and application elements in your environment?

■ Are you aligned with the owners of these systems?

■ Do you have real-time knowledge of changes being done to the infrastructure and applications?

■ Do you have monitoring gaps?

■ Which monitoring tools provide you with the best value?

Answering these questions involves overcoming fragmentation across teams of people, processes, and tools — essentially integrating ITSM and ITOM to enjoy the benefits of contextual full-stack visibility and streamlined processes within the organization.


The Right Combination

What is the right combination of people, processes, and tools we just discussed? Here are the two main guidelines:

Set up a major incident management team- to optimally benefit from your existing staff.

This team includes three vital roles:

- The incident manager/incident response commander. A designated role in charge of declaring a major incident and taking ownership of it. Their job is to essentially stop the bleeding of revenue and costs.

- The NOC/monitoring team. This is your front line of defense. When things go bump in the night or boom in the day, they're the ones picking it up with their “eyes on the glass” — 24/7. And they're in charge of reporting and creating full situational awareness for the incident command through bidirectional communications.

- The production support. The team that actually effects the required changes and executes the remediating action.


Deploy event correlation and automation tools to enable the incident management team.

These tools are key, allowing your team to do all the above.

First, correlate the alerts your monitoring and observability tools create into a drastically reduced number of high-level, insight-rich incidents by using Machine Learning and AI. Add context to these incidents by ingesting and understanding topology sources as well. This creates the needed full-stack visibility and situational awareness.

Then use ML and AI to determine the root cause of these incidents, including correlating them with data streams from your change tools: CI/CD, orchestration, change management, and auditing — to identify whether any changes were done in your environment are causing these incidents.

Finally — automate as many manual processes as you can to free your IT Ops team from time-consuming tasks. By integrating with collaboration tools — you can also enable the above-mentioned bi-directional communications.

The Latest

Two years ago, almost every customer conversation about AI started with the same questions: Which model should we use? What can it do? Is it ready for the enterprise? Today, those discussions have moved on. CIOs are far more interested in how to govern AI, integrate it with existing systems, prepare their workforce and make it part of everyday operations. The challenge is no longer to prove that AI can deliver value. It's instead about how to embed AI into the business in a way that's secure, scalable and delivers measurable outcomes ...


Two things happened to production incidents between 2023 and now, and they did not happen at the same speed. The first is that a class of dependency that barely existed three years ago now accounts for one incident in ten. Incidents disclosed by AI model and AI application providers rose from 1.7% of all disclosed unplanned incidents in 2023 to 10.7% in 2026 year to date, roughly a sixfold rise; that counts only incidents at AI companies themselves, so the true share is higher. The second is that the time to close an incident has not come down ...

When an AI assistant gives an incomplete or incorrect answer, teams often blame the model. They adjust prompts, switch models, increase context windows or test a new retrieval strategy. However the model may not be a problem. In many enterprise AI workflows, the problem begins inside the document-ingestion pipeline ...

If you talk to any security or observability teams right now, they're all fighting the same fire: their tooling was built to ingest X, but their sources are pumping Y and soon to be doing Z. The knee-jerk reaction is always the same: we need more platform. However, this reaction is wrong. Let me explain why, because the solution to this problem is foundational, not financial. Instead of hurling yet more money at the problem, make sure you've done what's needed upstream ...

Rapid AI adoption and the unique ways AI workloads operate is redefining the scope and structure of what these teams must deliver. This shift is forcing organizations to rethink how they manage scale, automation, and control, according to The State of SRE and Platform Engineering 2026, a new report from Dynatrace ...

AI is usually talked about as a software tool, but it also depends heavily on the network behind it. Whether a company is using AI for chatbots, automation, monitoring, analytics, or employee support, all of that information has to move across the network in a reliable and secure way. That means AI is not just an application decision. It is also an infrastructure decision. Before organizations rush into AI, they should ask a simple question: Is our network ready to support it? ...

Enterprise AI often lacks governed access to where business processes actually execute. Without that access, AI agents may be able to reason, but they cannot operate reliably across enterprise workflows. For AI agents to effectively carry out workflows, they will require integration-layer context and controls. Organizations can implement these prerequisites by providing AI with managed access to the middleware layer ...

Enterprise networks rarely behave the same way for very long. A routing adjustment in one region may unexpectedly alter application performance in another. A cloud migration may introduce hidden dependencies that go unnoticed until an outage occurs. All the while, the network is managed by several different teams, each of whom use different tool sets — and as a result, have different views of the network ... There’s usually an engineer who remembers why traffic fails over a certain way between sites, or which transparent firewall was added where. The problem is that human memory cannot scale alongside enterprise-scale networks ...

Ask an infrastructure team how confident they are in their ability to govern AI, and most will tell you they've got it handled. A recent survey of 406 IT decision-makers and platform engineering leaders found 86% expressing exactly that confidence. Ask the same group whether they have a formal written AI governance policy, and the number drops to 30%, according to Spacelift's Infrastructure Automation Report ...

In MEAN TIME TO INSIGHT Episode 27, Shamus McGillicuddy, EMA VP of Research, Network Infrastructure and Operations, and Parker Hathcock, EMA Research Director covering IT Service/Operations (ServiceOps), discuss observability unification in modern IT operations ...