

Resource Monitoring vs. Application Performance Monitoring (APM)

How Middleware Resource Monitoring is Different from APM
Ted Wilson

Is middleware resource monitoring the same thing as APM? No – but it is highly complementary with APM and organizations generally need both for complex, large-scale application environments that depend on middleware.

End to end resource monitoring is fundamentally different.

We see four general categories in the enterprise monitoring landscape:

1. Low level infrastructure monitoring, often open source or low-cost

2. Domain-specific admin and monitoring tools including database, server, log, and vendor-specific tools

3. Application-aware resource monitoring of infrastructure

4. APM, including transaction tracing and end-user monitoring

APM, and especially transaction monitoring, has its place. It is an important capability for some types of users such as developers who need to understand the behavior of their transactions and how they are performing. It is also very good at identifying code-based problems. If your problems are in the code, then APM can help. But what if the problem is not in the application itself but the infrastructure that supports that application? Most application performance issues are not code-based problems.

Oftentimes, the problems lie in the middleware tiers, servers and other resources. These are equally as important to monitor.

The Complexity of Middleware

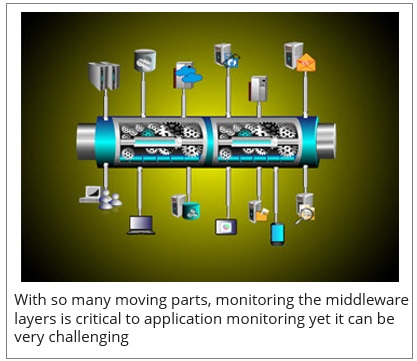
Middleware components are usually distributed, clustered and shared across multiple services and applications. Many organizations use middleware provided by multiple vendors across multiple tiers, on-premise, in the cloud, or hybrid. And a single middleware technology, such as TIBCO EMS, requires real-time and historical metric gathering for the EMS Servers, topics, queues, and destinations to really understand performance. An effective monitoring system will also provide information about other interdependencies. Is a problem with pending messages really occurring because of a CPU issue with a VMware host?

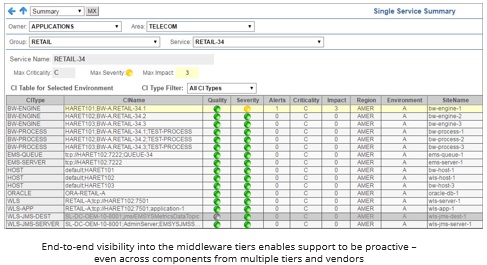
This all makes holistic monitoring tricky. So when an application problem lies in a middleware tier, your application support and middleware support teams require specialized tools to proactively identify the problem before the application is affected. If they are relying on end user or transaction monitoring for this type of problem, chances are the middleware components are going to be a black box. APM tools just don’t provide adequate visibility into the middleware.

So before you increase spending on APM tools, be sure you have the middleware tier covered and those support teams have the tools they need to be proactive in resolving the infrastructure level problems.

Ask yourself how you solve the majority of your Sev 1 incidents today. Are you using tools that help you understand the performance of your clustered middleware? Or are you using tools that help you understand your transactions and transaction throughput? The answer may help you in prioritizing your monitoring investments.

Ted Wilson is Chief Operating Officer at SL Corporation.

Hot Topics

The Latest

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...

Government agencies are largely misjudging their level of AI governance as the technology permeates their organization, according to Racing to Deploy: How Public Sector AI Adoption is Moving Faster Than the Foundations Needed to Support It, a new report from SolarWinds ...

Resource Monitoring vs. Application Performance Monitoring (APM)

How Middleware Resource Monitoring is Different from APM
Ted Wilson

Is middleware resource monitoring the same thing as APM? No – but it is highly complementary with APM and organizations generally need both for complex, large-scale application environments that depend on middleware.

End to end resource monitoring is fundamentally different.


We see four general categories in the enterprise monitoring landscape:

1. Low level infrastructure monitoring, often open source or low-cost

2. Domain-specific admin and monitoring tools including database, server, log, and vendor-specific tools

3. Application-aware resource monitoring of infrastructure

4. APM, including transaction tracing and end-user monitoring

APM, and especially transaction monitoring, has its place. It is an important capability for some types of users such as developers who need to understand the behavior of their transactions and how they are performing. It is also very good at identifying code-based problems. If your problems are in the code, then APM can help. But what if the problem is not in the application itself but the infrastructure that supports that application? Most application performance issues are not code-based problems.

Oftentimes, the problems lie in the middleware tiers, servers and other resources. These are equally as important to monitor.

The Complexity of Middleware

Middleware components are usually distributed, clustered and shared across multiple services and applications. Many organizations use middleware provided by multiple vendors across multiple tiers, on-premise, in the cloud, or hybrid. And a single middleware technology, such as TIBCO EMS, requires real-time and historical metric gathering for the EMS Servers, topics, queues, and destinations to really understand performance. An effective monitoring system will also provide information about other interdependencies. Is a problem with pending messages really occurring because of a CPU issue with a VMware host?

This all makes holistic monitoring tricky. So when an application problem lies in a middleware tier, your application support and middleware support teams require specialized tools to proactively identify the problem before the application is affected. If they are relying on end user or transaction monitoring for this type of problem, chances are the middleware components are going to be a black box. APM tools just don’t provide adequate visibility into the middleware.

So before you increase spending on APM tools, be sure you have the middleware tier covered and those support teams have the tools they need to be proactive in resolving the infrastructure level problems.

Ask yourself how you solve the majority of your Sev 1 incidents today. Are you using tools that help you understand the performance of your clustered middleware? Or are you using tools that help you understand your transactions and transaction throughput? The answer may help you in prioritizing your monitoring investments.


Ted Wilson is Chief Operating Officer at SL Corporation.

Hot Topics

The Latest

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...

Government agencies are largely misjudging their level of AI governance as the technology permeates their organization, according to Racing to Deploy: How Public Sector AI Adoption is Moving Faster Than the Foundations Needed to Support It, a new report from SolarWinds ...