
MELTDOWN: Single Software Update Causes Largest IT Outage in History

Pete Goldin
APMdigest

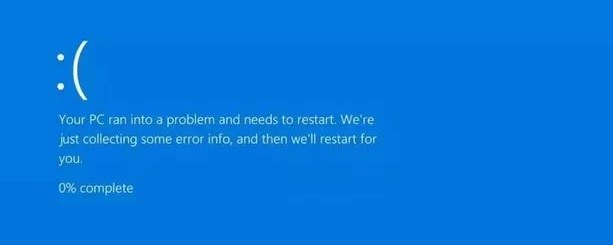
A defective software update caused what some experts are calling the largest IT outage in history on Friday, July 19. The impact reverberated through multiple industries around the world. Thousands of flights were canceled. TV stations went offline. Some 911 systems were down. Hospital operations were disrupted. Bank accounts were inaccessible. Many businesses and government services were unable to function.

The problem started with a bug in an automatic update for CrowdStrike's Falcon sensor — which is used to block online cyberattacks — and quickly escalated globally, causing Microsoft Windows systems to crash. CrowdStrike confirmed that the cause was a defect in a single content update for Windows hosts, not a security incident or cyberattack.

The Automation Challenge

"As companies transition to products with fully automated updates, they gain touchless update and patch remediation. However, automation is useless if it's supplied with bad content or configuration," said Kent Feid, Senior Director of Product Management at Quest.

"This event demonstrates that even the best companies can push out patches that cripple environments and, at times, entire essential service industries, and highlights the need for a balance between control and automation when it comes to software releases. While automation is necessary, it is the balanced approach that provides the best control and minimizes risk."

The issue also shines a spotlight on quality assurance. "A simple defect found in a single content update for Windows hosts was enough to cause havoc globally. The lesson to be learned is to integrate quality assurance into the software development lifecycle and to assure business outcomes not just technology," said Tom Reuner, Executive Research Leader, HFS Research.

Managing and Controlling Change

This massive outage shows how relying on outside services can cause major problems — something Catchpoint has been warning companies about for a long time.

At any moment, even the smallest oversight or piece of unpreparedness can bring systems — and consequently businesses — down

"The scale of today's global IT outage is unparalleled in recent history. It serves as a stark reminder that our entire world is powered by digital experiences and that the internet is neither magically infallible nor inherently resilient. This is a reminder you need to manage and control change: Don't blindly update software or change configuration," Mehdi Daoudi, CEO of Catchpoint, said on Friday. "At any moment, even the smallest oversight or piece of unpreparedness can bring systems — and consequently businesses — down."

Image removed.

Daoudi continued, "Preparation and visibility are key, not just to prevent such outages but to mitigate the vast financial risks they pose. The fallout from today's event will likely be measured not just in the disruption of services but in exponential financial losses worldwide, potentially amounting to millions or even billions in lost revenue. It highlights a critical vulnerability: our increasing dependency on digital infrastructure can translate into staggering costs when that infrastructure fails."

Real-Time Observability

"The massive Microsoft outage, caused by a faulty CrowdStrike update, underscores the new reality companies face: globally distributed software platforms that drive business today are a complex web of interdependencies, not all of which are under any one actor's control," explained Antony Falco, VP at Hydrolix.

"A modest mistake can literally grind global business to a halt. The monitoring and observability solutions we rely on to spot these modest mistakes and critical issues have struggled to keep up, even with systems of smaller scale. Clearly we need a new approach to observability — one that is real-time and can simplify the management of tremendous volumes of data streaming in from myriad sources so events can be detected and mitigated before they spread."

Redundancy and Diversity

In addition, this type of event demonstrates that for critical services, redundancy and diversity are key, according to Olaf Kolkman, Principal - Internet Technology, Policy, and Advocacy, and Dan York, Director, Internet Technology, both from the Internet Society. "We need diversity across all aspects of tech, including the operating systems. For example, systems using Linux or Mac OS were not affected by this particular issue. We need to ensure that our systems and networks use a range of different products and services so that an issue with one system will not bring them all down."

They added, "The reality is that in our world of complex, interconnected systems, incidents like this happen. They have happened in the past and they will happen in the future. The important part is how we learn from them and how we improve the resilience of our systems, so that similar issues do not happen again."

The Cost of Downtime

Just as a final thought, I would point out that several recent reports have shown that the cost of downtime is high, and downtime can impact companies in many ways. Catchpoint's Internet Resilience Report 2024 found that almost half of survey respondents said outages cost them from $1 million to $10 million every month.

Similarly, Splunk's recent report, The Hidden Costs of Downtime calculates lost revenue due to downtime averages $49 million, regulatory fines average $22 million, and missed SLA penalties average $16 million annually.

Downtime also negatively impacts customer experience, employee productivity, innovation, brand reputation and even share value. In fact, AP reported that shares of CrowdStrike stock fell nearly 10% on Friday, and Microsoft stock fell more than 3%. These numbers speak louder than words.

Pete Goldin is Editor and Publisher of APMdigest

The Latest

AI observability serves several roles across an organization. AI engineers use it to build, evaluate, and improve AI systems. SREs use it to operate those systems reliably and efficiently in production, including managing their cost. Leaders need it to connect AI behavior and operational performance to business outcomes. The common need is a clear understanding of whether AI systems are delivering the intended result ...

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...

MELTDOWN: Single Software Update Causes Largest IT Outage in History

Pete Goldin
APMdigest

A defective software update caused what some experts are calling the largest IT outage in history on Friday, July 19. The impact reverberated through multiple industries around the world. Thousands of flights were canceled. TV stations went offline. Some 911 systems were down. Hospital operations were disrupted. Bank accounts were inaccessible. Many businesses and government services were unable to function.

The problem started with a bug in an automatic update for CrowdStrike's Falcon sensor — which is used to block online cyberattacks — and quickly escalated globally, causing Microsoft Windows systems to crash. CrowdStrike confirmed that the cause was a defect in a single content update for Windows hosts, not a security incident or cyberattack.


The Automation Challenge

"As companies transition to products with fully automated updates, they gain touchless update and patch remediation. However, automation is useless if it's supplied with bad content or configuration," said Kent Feid, Senior Director of Product Management at Quest.

"This event demonstrates that even the best companies can push out patches that cripple environments and, at times, entire essential service industries, and highlights the need for a balance between control and automation when it comes to software releases. While automation is necessary, it is the balanced approach that provides the best control and minimizes risk."

The issue also shines a spotlight on quality assurance. "A simple defect found in a single content update for Windows hosts was enough to cause havoc globally. The lesson to be learned is to integrate quality assurance into the software development lifecycle and to assure business outcomes not just technology," said Tom Reuner, Executive Research Leader, HFS Research.

Managing and Controlling Change

This massive outage shows how relying on outside services can cause major problems — something Catchpoint has been warning companies about for a long time.

At any moment, even the smallest oversight or piece of unpreparedness can bring systems — and consequently businesses — down

"The scale of today's global IT outage is unparalleled in recent history. It serves as a stark reminder that our entire world is powered by digital experiences and that the internet is neither magically infallible nor inherently resilient. This is a reminder you need to manage and control change: Don't blindly update software or change configuration," Mehdi Daoudi, CEO of Catchpoint, said on Friday. "At any moment, even the smallest oversight or piece of unpreparedness can bring systems — and consequently businesses — down."

Image removed.

Daoudi continued, "Preparation and visibility are key, not just to prevent such outages but to mitigate the vast financial risks they pose. The fallout from today's event will likely be measured not just in the disruption of services but in exponential financial losses worldwide, potentially amounting to millions or even billions in lost revenue. It highlights a critical vulnerability: our increasing dependency on digital infrastructure can translate into staggering costs when that infrastructure fails."

Real-Time Observability

"The massive Microsoft outage, caused by a faulty CrowdStrike update, underscores the new reality companies face: globally distributed software platforms that drive business today are a complex web of interdependencies, not all of which are under any one actor's control," explained Antony Falco, VP at Hydrolix.

"A modest mistake can literally grind global business to a halt. The monitoring and observability solutions we rely on to spot these modest mistakes and critical issues have struggled to keep up, even with systems of smaller scale. Clearly we need a new approach to observability — one that is real-time and can simplify the management of tremendous volumes of data streaming in from myriad sources so events can be detected and mitigated before they spread."

Redundancy and Diversity

In addition, this type of event demonstrates that for critical services, redundancy and diversity are key, according to Olaf Kolkman, Principal - Internet Technology, Policy, and Advocacy, and Dan York, Director, Internet Technology, both from the Internet Society. "We need diversity across all aspects of tech, including the operating systems. For example, systems using Linux or Mac OS were not affected by this particular issue. We need to ensure that our systems and networks use a range of different products and services so that an issue with one system will not bring them all down."

They added, "The reality is that in our world of complex, interconnected systems, incidents like this happen. They have happened in the past and they will happen in the future. The important part is how we learn from them and how we improve the resilience of our systems, so that similar issues do not happen again."

The Cost of Downtime

Just as a final thought, I would point out that several recent reports have shown that the cost of downtime is high, and downtime can impact companies in many ways. Catchpoint's Internet Resilience Report 2024 found that almost half of survey respondents said outages cost them from $1 million to $10 million every month.

Similarly, Splunk's recent report, The Hidden Costs of Downtime calculates lost revenue due to downtime averages $49 million, regulatory fines average $22 million, and missed SLA penalties average $16 million annually.

Downtime also negatively impacts customer experience, employee productivity, innovation, brand reputation and even share value. In fact, AP reported that shares of CrowdStrike stock fell nearly 10% on Friday, and Microsoft stock fell more than 3%. These numbers speak louder than words.

Pete Goldin is Editor and Publisher of APMdigest

The Latest

AI observability serves several roles across an organization. AI engineers use it to build, evaluate, and improve AI systems. SREs use it to operate those systems reliably and efficiently in production, including managing their cost. Leaders need it to connect AI behavior and operational performance to business outcomes. The common need is a clear understanding of whether AI systems are delivering the intended result ...

Part 4 outlines the challenges enterprise face when adopting AI observability. The main challenge is that AI complexity compounds at every stage of maturity. LLM-based applications introduce new behavior, dependencies, and quality considerations, while Agentic AI adds further failure modes as systems make decisions and take actions ...

Part 3 reports on the current state of AI observability. Most experts agree: enterprises are moving faster with AI than they are with the operational discipline needed to run it safely ...

When discussing AI Observability, one of the first questions that arises: Is this just an extension of traditional observability or is this a whole new type of tool? Part 2 compares traditional observability with AI observability ...

In this extensive 14-part series that will post over the next three weeks, experts across observability and AI will provide insight and opinions on the need for AI Observability, the challenges, the benefits, the current state, and predictions for the future ...

Amid rising complexity, organizations are moving quickly toward agent-driven operations: AgenticOps, according to The Impact of Agentic AI on Network Operations, a new report from Cisco ...

AI, automation, and enterprise software give organizations an extraordinary amount of leverage. Work that once required hours can happen in minutes. Information buried across systems can be analyzed almost instantly. Complex workflows can be coordinated across teams with far less manual intervention. That leverage creates a temptation to start with the technology ...

Everyone wants to talk about models. Compute clusters. Benchmark scores that climb a fraction of a point and make headlines anyway. It's an easy conversation to have because it's measurable. But it's also increasingly beside the point ...

For more than a decade, the default infrastructure play has been simple. Move more workloads to the cloud, retire on-premises gear and treat the data center as a cost to shrink. That logic held while public cloud offered near-limitless capacity at predictable prices, and AI demand is now testing both halves of that assumption ...

Most enterprise IT leaders can tell you exactly how many applications are running across their organization. They can surface a dashboard showing telecom spend by region, pull a report on SaaS license utilization, or call up a real-time view of mobile device inventory. The data is there, and IT leaders have largely delivered on the promise of visibility. Yet, in most organizations, that visibility has not translated into business value ...